CatalogStacksModulesSaaSMobileLabs → Become a partner
Home›Catalog›🎚️ LLM fine-tuning›Unsloth
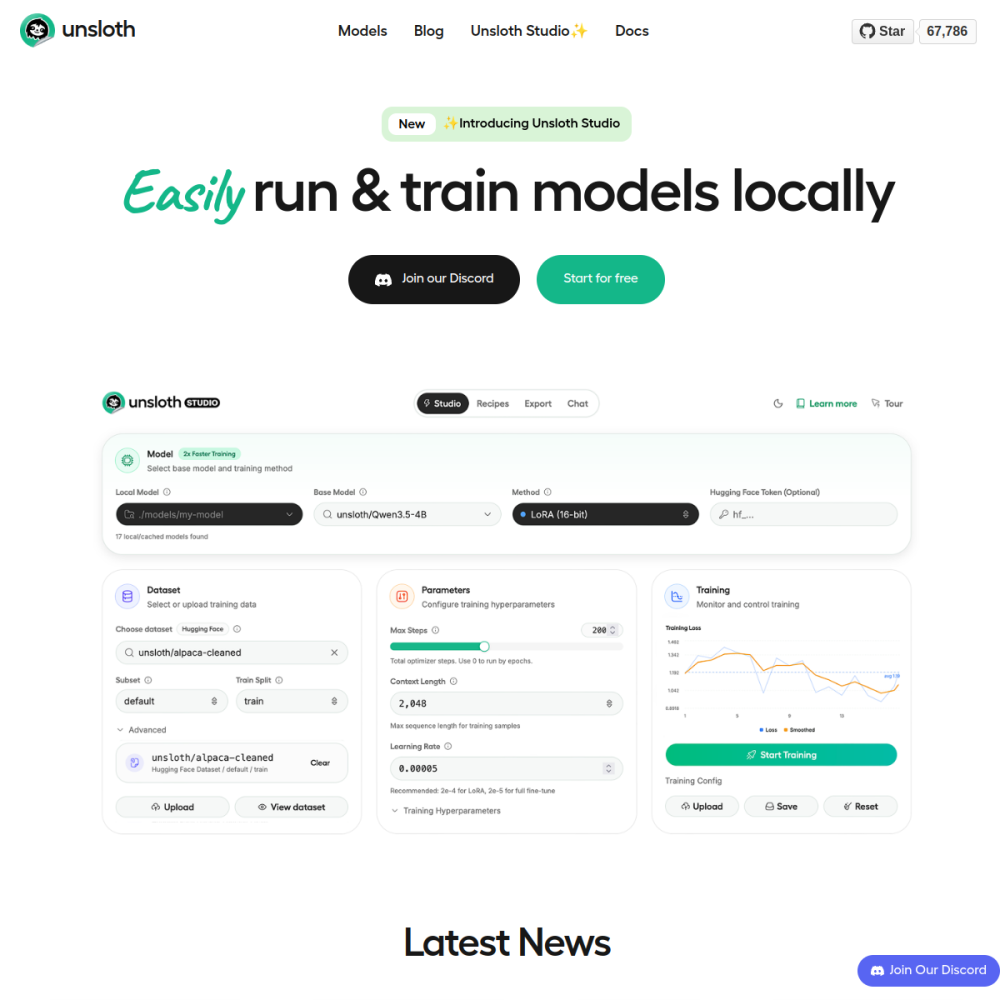
Screenshot of Unsloth

// official site: unsloth.ai ↗

LLM FINE-TUNING · PRO TIER

Unslothpro

Unsloth is the fastest LLM fine-tuning library — custom Triton kernels deliver 2× the speed and 50% less VRAM than vanilla HuggingFace + PEFT. Maintained by Unsloth AI (Daniel Han, ex-Microsoft). The library of choice when budget GPU + speed matter.

🎚️ LLM fine-tuning Min 16384 MB RAM Port 8889 (http) Tier pro
// What it is

A closer look.

Unsloth is the fastest LLM fine-tuning library — custom Triton kernels deliver 2× the speed and 50% less VRAM than vanilla HuggingFace + PEFT. Maintained by Unsloth AI (Daniel Han, ex-Microsoft). The library of choice when budget GPU + speed matter.

For solo developers and AI tinkerers fine-tuning on Colab/consumer GPUs, Unsloth is the canonical choice.

// Use cases

What it's for.

Concrete scenarios where teams pick Unsloth over the SaaS alternative.

◆

Lightning-fast LoRA training

2-5× faster than alternatives
◈

Low VRAM training

7B QLoRA on 8 GB VRAM (vs 24 GB elsewhere)

◇

Pre-quantized models

load 4-bit base instantly (no quantize-at-load delay)

▣

Native multi-GPU

added Q4 2024

▦

Broad model support

Llama, Mistral, Qwen, Phi, Gemma all covered

▩

TRL integration

SFT, DPO, ORPO via TRL trainers

// Who it's for

Built for these teams.

If your team profile matches one of these, Unsloth is a strong fit out of the box.

Profile A

Solo AI developers

fine-tuning on consumer GPUs

Profile B

Researchers

running fine-tuning experiments on a budget

Profile C

Startups

wanting fastest iteration on training experiments

Profile D

Educators

running fine-tuning workshops on shared hardware

Profile E

Hosting providers

offering low-cost fine-tuning tier

// Differentiators

Why teams pick Unsloth.

When evaluating self-hosted options for this category, here are the dimensions on which Unsloth consistently lands above the alternatives.

  • ✓Apache 2.0 — fully open
  • ✓Fastest — 2-5× speedup vs standard transformers + PEFT
  • ✓Lowest VRAM — 50% less than alternatives
  • ✓Pre-quantized HF models — at unsloth/* namespace (instant load)
  • ✓Active development — frequent releases, Triton kernel optimizations
  • ✓Daniel Han backing — known LLM optimization expert
  • ✓Notebook library — Colab-ready examples for common tasks
// Integrations

Connects to.

The stack you'll plug Unsloth into — services, protocols, and adjacent apps in the BluixApps catalog.

◇
HuggingFace Transformers
base
◈
PEFT + TRL
LoRA + SFTTrainer
◆
Pre-quantized models
at unsloth/* HF namespace
▣
Pair with
vLLM/TGI to serve fine-tuned (Unsloth → save_pretrained_merged → load with vLLM)
▦
DPO/ORPO support
via TRL
▩
Continued pretraining
for domain-adapt
// Adoption & deployment

Notable users & community

  • 24k+ GitHub stars
  • Unsloth AI corporate backing
  • Daniel Han (ex-Microsoft) leads development
  • Featured in popular Colab fine-tuning tutorials
  • Active Discord + Reddit presence

What we ship

  • Docker (pytorch base + Unsloth pip-installed at runtime)
  • JupyterLab pre-installed for interactive notebooks
  • Persistent volumes: workspace, datasets, outputs
  • Port 8889 mapped
  • Pre-set HF_TOKEN environment variable for gated models
  • Install report at /root/bluixapps/unsloth.txt
  • Full Python quick-start example (paste into Jupyter)
  • Notebook library URL for premade Colab-ready examples
  • Pairing notes (vLLM/TGI for serving merged model)
  • GPU pre-flight check via bluixapps_ensure_nvidia_runtime
  • Backup hook covers workspace + outputs
// Tips & operations

Run it properly.

Operational guidance from running this in production — what to lock down, what surprises people.

// PERFORMANCE
VRAM with Unsloth
// SECURITY
Pre-quantized models
unsloth/Meta-Llama-3.1-8B-Instruct-bnb-4bit loads in seconds
// OPERATIONS
Code pattern
from FastLanguageModel.from_pretrained() → get_peft_model() → TRL SFTTrainer
// RELIABILITY
Multi-GPU
enable in newer versions via tensor_parallel
// DEPLOYMENT
Save
model.save_pretrained_merged() to export combined weights
// SCALING
vs Axolotl
Unsloth = code/library, Axolotl = config-driven. Use Unsloth for speed-critical custom code; Axolotl for reproducible config workflows
// MAINTENANCE
vs LLaMA-Factory
Unsloth = library; LLaMA-Factory = visual UI on top
16384
// min ram (MB)
60
// min disk (GB)
8889
// access port
http
// protocol
pro
// bluixapps tier

Project resources

Official siteunsloth.ai ↗
↑